

Our works
We build AI that does the work
Products we built and still run, and the small models we trained to do one job each.
Grouped by the job they do
Works
Real systems we built. Most are our own products, and the badge on each one says whether you can try it.
AI on hardware you own
Picking the hardware, measuring it, checking what the model says, and training models small enough to run on it, from a desk-side box to a phone.
Models we trained
Each one trained for a single job, then run on the hardware in front of it, from a desk-side box to a player's phone.
Judgment QC Gate
Open weightsA 4B review model fine-tuned on our own approved decisions
We fine-tuned Qwen3-4B on our own approved review decisions, then quantized it to run on a desk-side AMD box. It checks a coding agent's work before the reply goes out, and a failing verdict sends the work back to be fixed. It has been the live gate on our own agents since July. The weights are public under Apache-2.0, and the model card lists the limits of a small probe set.
- Catches
- 12 / 12
- False blocks
- 0 / 30
- Build
- 4.3 GB
MiniHood Pet Model
LiveA 0.5B chat model distilled from a 32B one to run inside a phone browser
Pets in MiniHood, our browser game, talk back. We had a 32B model write pet chats, trained Qwen2.5-0.5B on them (distillation) and packed it into a 290 MB build that a phone downloads once and runs in the browser through WebGPU, so the reply is written on the player's own device. Scored blind on 40 held-out chats, it averaged 4.5 out of 5 against 2.2 for the stock model.
- Blind score
- 4.5 vs 2.2
- Download
- 290 MB, once
- Runs on
- The player's phone
Singapore Image Model
Not publicAn image LoRA trained on the everyday Singapore look
Stock image models kept drawing Singapore scenes that did not look like Singapore. We trained a rank-32 LoRA on Qwen-Image with 1,851 openly licensed Singapore photos, in under three hours on one rented H100, and ran it on our own box for the scene images in our short news videos. It has not been scored against a benchmark.
- Training photos
- 1,851
- Training cost
- About US$12
- Runs on
- Our own box
Agents that do the work
Agents that read the inbox, draft the reply, match the jobs, answer shoppers and take the bookings.
 Not public
Lyra
Agent-driven CRM + ERP we run Altronis on
FastAPI + React, built to be run by AI agents, with an audit trail on every write. It pulls in email, drafts replies with the full thread in view, puts the drafts in Outlook, preps each meeting a day ahead, and needs the owner's approval before anything is marked paid. It runs on our own server.
- Hosting
- Our own server
- Meeting prep
- A day ahead
- Audit trail
- Every write
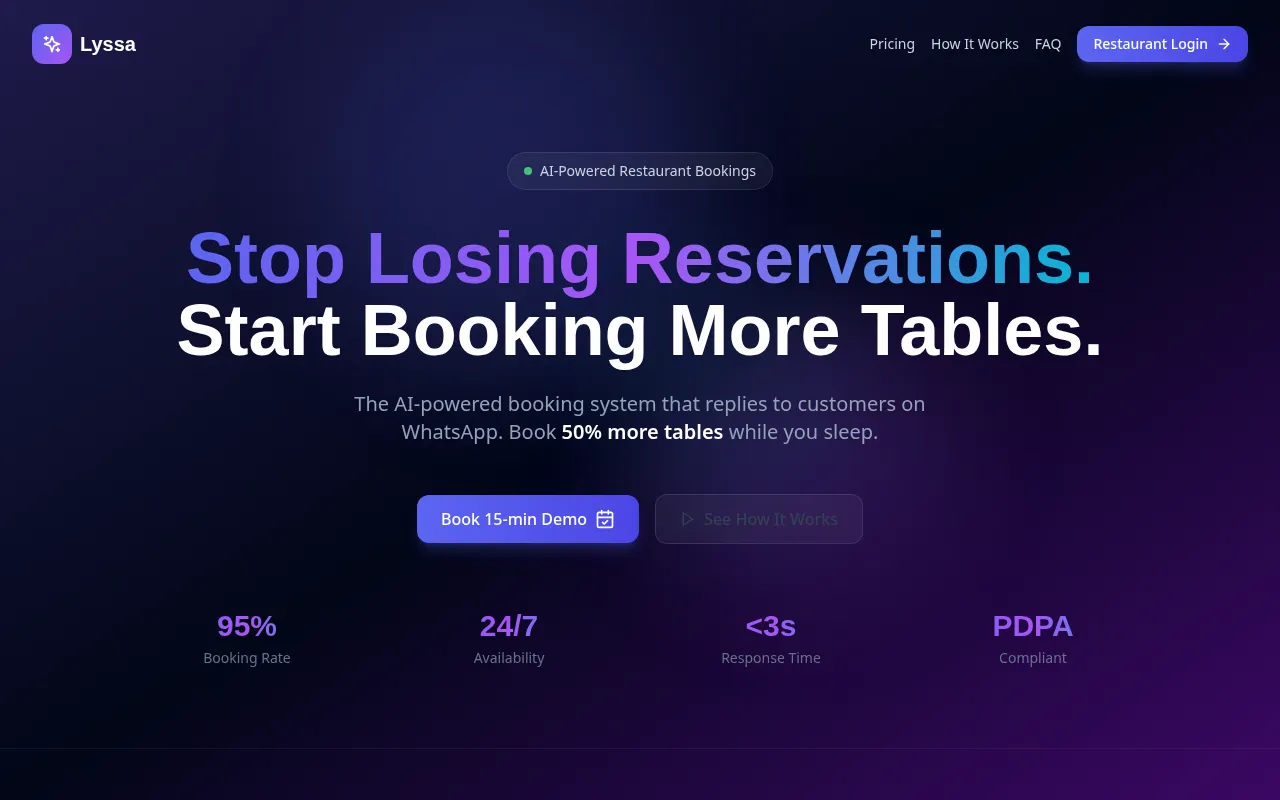 Not public
Lyssa
AI Reservations for Restaurants
Industry: F&BA booking assistant that answers diners on WhatsApp in plain language, takes the booking and copes when they change their mind mid-chat. Each restaurant gets its own Firebase project, so its diner data stays separate, and sensitive fields are encrypted at rest. Built for Singapore F&B operators.
- Channel
- Diner data
- Kept per restaurant
- Sensitive fields
- Encrypted at rest
Assistants that research and explain
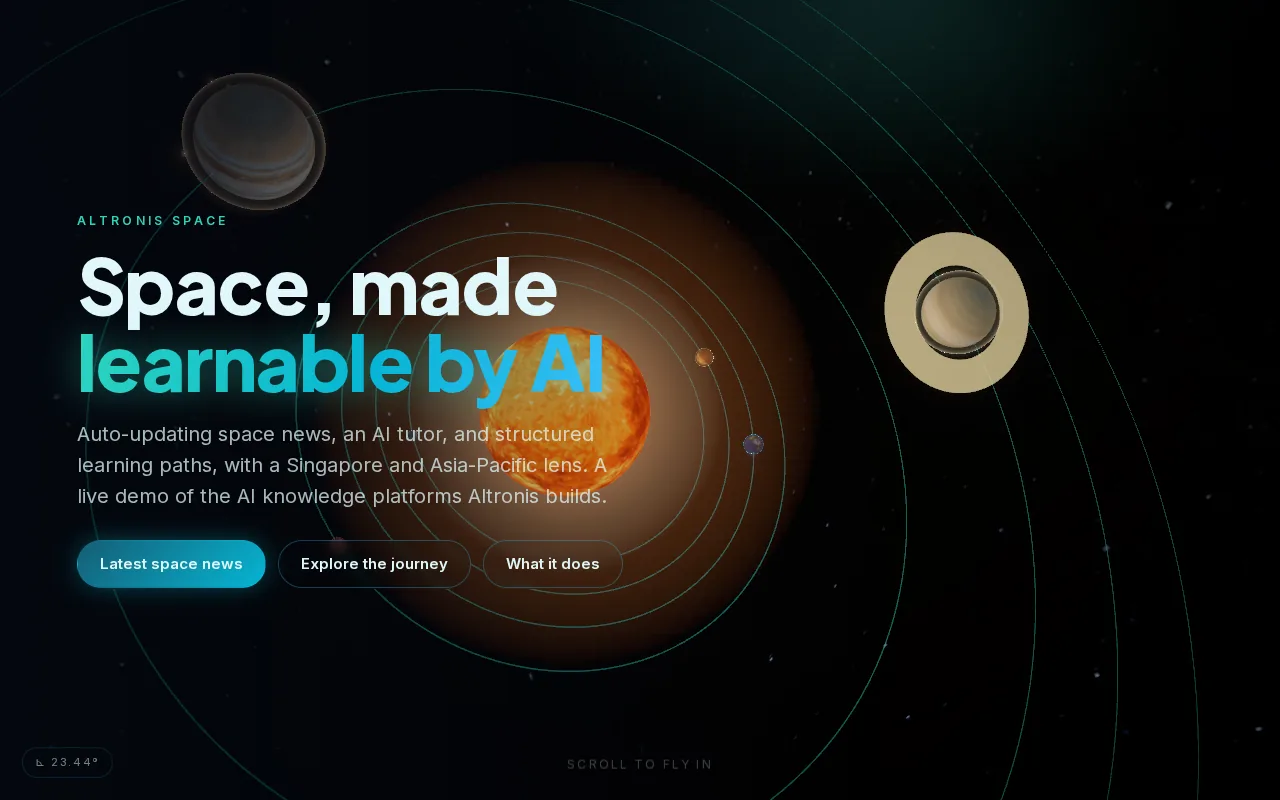
Assistants that do the digging and explain the answer in plain words, on stock moves and space.

Apps we shipped end to end
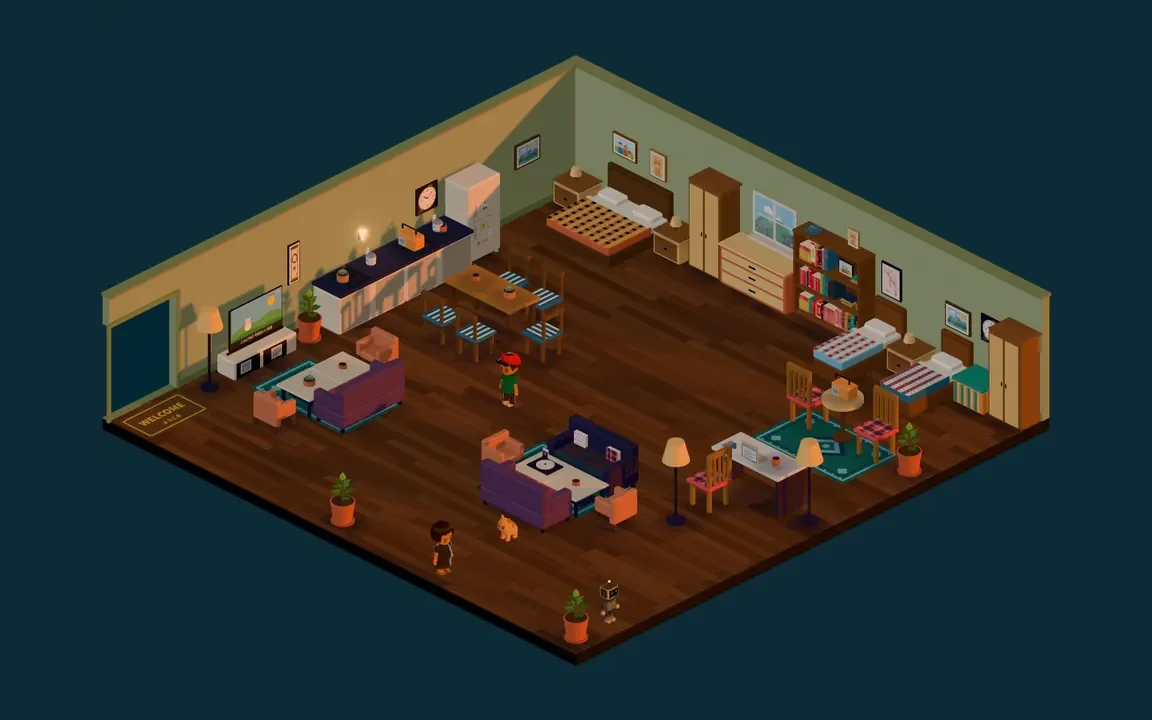
Apps we took from idea to live ourselves, from the design to the hosting.
Security we run on ourselves
The checker we run every morning on our own public sites, and the tests it can run against an AI chat.
Vedis
Not publicSecurity checks we run on our own systems every morning
Every morning it scans our public sites for weak settings, exposed files and certificate problems, compares the result with yesterday and alerts us on anything new. It reads the day's security advisories and drafts new tests, and none runs until a person has reviewed it. It can also attack an AI chat the way an attacker would, trying prompt injection, jailbreaks and data leaks, and a finding counts only when at least two of three separate checks uphold it.
- Runs
- Every morning
- New tests
- Reviewed by a person
- Findings
- 2 of 3 checks agree
Earlier builds
Tools from before the current line-up, kept for the record.

AI Foundry
Enterprise AI Initiative Management
Enterprise-grade platform for managing AI initiatives across corporate functions. End-to-end visibility into the AI lifecycle, from ideation through deployment to sustaining operations.

Thirty minutes, no slides, no obligation
Tell us what is slow, costly or broken.